What This Workflow Does
This automated workflow solves the challenge of consistently evaluating language model performance at scale. Instead of manual testing, it systematically assesses LLM responses using GPT-4 as an objective judge, then logs all results in Google Sheets for analysis. The solution saves AI teams dozens of hours per week while providing more consistent, data-driven evaluations than human testing alone.
By automating the entire testing pipeline - from running test cases through the target LLM to scoring responses and recording outcomes - teams gain continuous visibility into model performance. The workflow helps identify regression issues quickly, measure the impact of prompt engineering changes, and compare different model versions quantitatively.
How It Works
1. Load Test Cases
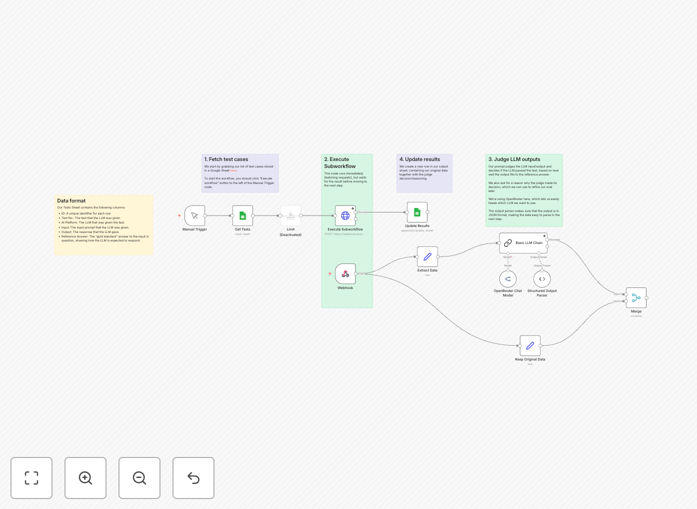
The workflow begins by reading a predefined set of test cases from your Google Sheet. These represent the full range of queries your LLM should handle, including edge cases and known problem areas.
2. Execute LLM Queries
Each test case is sent to your target language model (ChatGPT, Claude, or custom LLM) through its API. The workflow handles all API communication and error handling automatically.
3. GPT-4 Evaluation
Responses are then evaluated by GPT-4 acting as an impartial judge. The workflow provides GPT-4 with specific scoring criteria (accuracy, relevance, etc.) to ensure consistent evaluations.
4. Results Logging
All test results are written back to Google Sheets with timestamps, scores, and the full conversation history. This creates a searchable performance database for trend analysis.
Who This Is For
This workflow is ideal for:
- AI product teams deploying LLM-powered features
- Prompt engineers optimizing model performance
- QA teams responsible for AI system testing
- Researchers comparing different model versions
- Startups needing affordable LLM evaluation
Pro tip: Use the historical data in Sheets to create automated performance dashboards with Data Studio or Looker for stakeholder reporting.
What You'll Need
- n8n instance (cloud or self-hosted)
- Google Sheets with test cases
- API access to your target LLM
- OpenAI API key for GPT-4 evaluation
Quick Setup Guide
- Download the JSON workflow file
- Import into your n8n instance
- Connect your Google Sheets and API credentials
- Configure your test case spreadsheet format
- Set your evaluation criteria in the GPT-4 judge node
- Run initial test and verify results
Key Benefits
90% time savings compared to manual LLM testing processes. What took days can now run automatically overnight.
Objective scoring eliminates human rater bias and fatigue, with GPT-4 applying the same standards to every evaluation.
Historical tracking in Sheets creates an auditable performance record for compliance and improvement tracking.
Scalable testing allows expanding test coverage without proportional increases in effort or cost.