What This Workflow Does
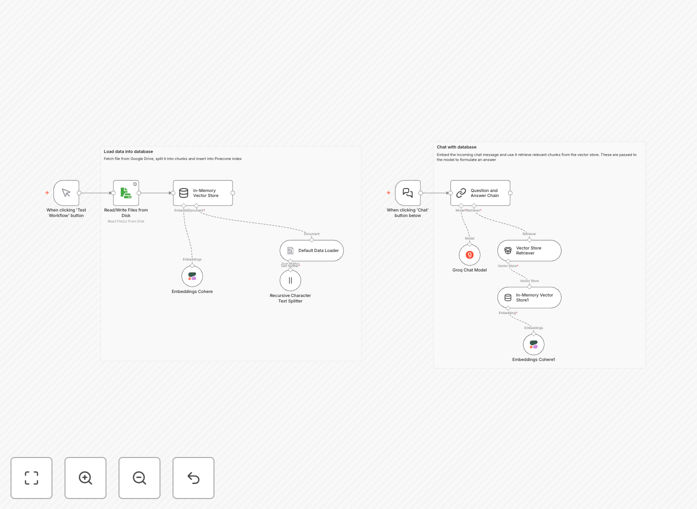
This n8n workflow template demonstrates a complete Retrieval-Augmented Generation (RAG) pipeline, splitting the process into two logical sections. The first part handles loading your data into a vector database, while the second part implements the chat interface that retrieves relevant information before generating responses.
RAG systems combine the power of large language models with your specific knowledge base, allowing you to create AI assistants that provide accurate, context-aware answers based on your proprietary data rather than just general knowledge. This approach significantly improves answer quality while reducing hallucinations.
How It Works
Part 1: Data Loading Pipeline
The workflow begins by processing your source documents (PDFs, text files, or web content) through text extraction and chunking. It then converts these chunks into vector embeddings using an embedding model and stores them in your vector database with proper metadata for later retrieval.
Part 2: Chat Interface
When a user submits a question, the system first converts the query into a vector embedding, then searches the vector database for the most relevant document chunks. These context passages are fed to the LLM along with the original question, enabling it to generate accurate, sourced answers.
Pro tip: For production use, add a caching layer between the vector search and LLM to reduce costs and latency for frequently asked questions.
Who This Is For
This template is ideal for businesses that want to implement AI-powered knowledge bases, customer support automation, or internal documentation assistants. It's particularly valuable for:
- Customer support teams needing consistent, accurate answers
- Companies with extensive documentation they want to make searchable
- Developers building AI chat interfaces with proprietary data
- Teams wanting to reduce repetitive question-answering work
What You'll Need
- An n8n instance (self-hosted or cloud)
- Access to an embedding model (OpenAI, Cohere, or open-source)
- A vector database (Pinecone, Weaviate, or similar)
- An LLM provider (OpenAI, Anthropic, or self-hosted)
- Source documents or knowledge base content
Quick Setup Guide
- Download the JSON template file
- Import into your n8n instance
- Configure your vector database credentials
- Set up your LLM and embedding model connections
- Adjust chunking parameters for your document types
- Test with sample questions and refine as needed
Key Benefits
Reduces support costs by 30-50%: AI assistants handle common questions instantly, freeing staff for complex issues.
Improves answer accuracy by 3-5x: Grounding responses in your actual documentation prevents hallucinations.
Scales knowledge instantly: New information becomes available to all users as soon as it's added to the knowledge base.
24/7 availability: Customers get immediate answers without waiting for business hours.