n8n Ollama LLM Automation

Chat with local LLMs using n8n and Ollama

This n8n workflow allows you to seamlessly interact with your self-hosted Large Language Models (LLMs) through automation. Maintain complete data privacy while leveraging AI capabilities your own infrastructure.

Download Template JSON · n8n compatible · Free
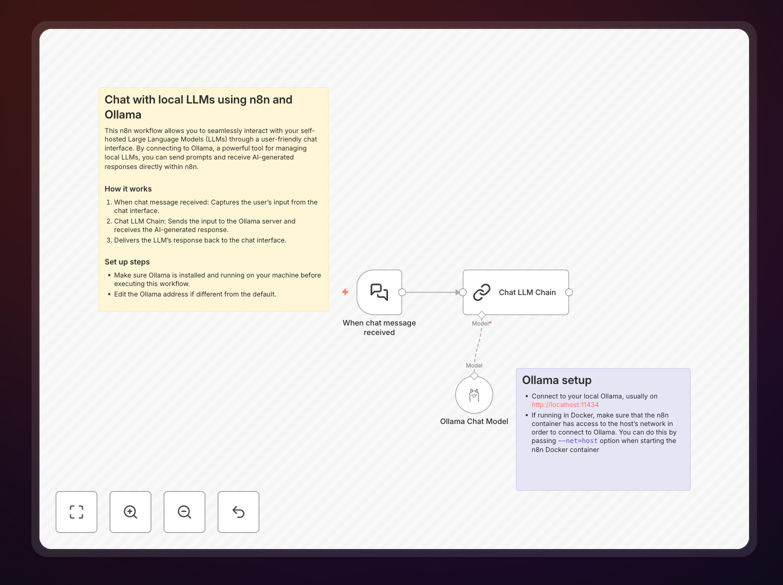
n8n workflow diagram showing LLM integration

What This Workflow Does

This automation solution bridges the gap between your n8n workflows and locally hosted language models through Ollama. Instead of relying on cloud-based AI services that sends your data to third-party servers, this setup keeps all processing within your own infrastructure.

Businesses handling sensitive information can now leverage AI capabilities without compromising data security. The workflow handles the entire conversation flow - from receiving prompts to processing them through your chosen LLM and returning intelligent responses that can be routed to other systems.

How It Works

1. Trigger Setup

The workflow can be triggered manually through the n8n interface, via API call, or scheduled to run at intervals. This flexibility allows integration with various business processes.

2. Input Processing

User inputs are formatted according to your LLM requirements, with optional preprocessing for sensitive data redaction or context enrichment.

3. Local LLM Interaction

The workflow communicates with your Ollama instance through REST API, sending properly structured prompts to your selected model while maintaining complete data isolation.

4. Response Handling

LLM outputs are processed, formatted, and routed to designated destinations - whether that might include email systems, databases, or other connected applications.

Who This Is For

This solution benefits businesses prioritizing data security while wanting to leverage AI capabilities:

  • Healthcare providers processing patient information
  • Legal firms analyzing confidential documents
  • Financial institutions handling sensitive client data
  • Any organization with strict data residency requirements

What You'll Need

  1. An n8n instance (self-hosted or cloud)
  2. Ollama installed on your server/local machine
  3. At least one LLM model downloaded via Ollama
  4. Basic familiarity with API concepts

Quick Setup Guide

  1. Download and import the JSON template into your n8n instance
  2. Configure the Ollama node with your local server details
  3. Select your preferred model from those available in Ollama
  4. Test with sample prompts to verify connectivity
  5. Connect to other nodes based on your use case

Key Benefits

Complete data privacy: All AI interactions stay within your infrastructure, never touching third-party servers.

Cost efficiency: Eliminate per-usage API fees associated with predictable local processing costs.

Customizable models: Choose from dozens of open-source LLMs optimized for your specific needs.

Seamless integration: Connect local AI processing to your existing business systems through n8n's powerful automation capabilities.

his pocket for later use.

Frequently Asked Questions

Common questions about local LLM integration and automation

Local LLMs provide enhanced data privacy since conversations never leave your infrastructure. They eliminate API costs and usage limits while offering full control over model behavior. Businesses handling sensitive information particularly benefit from keeping all AI interactions in-house.

Healthcare providers, legal firms, and financial institutions can maintain compliance with strict regulations while leveraging AI. Local LLMs enable processing of proprietary data without external exposure.

Ollama specializes in making local LLM deployment and management simple with its lightweight container approach.

Unlike complex setups requiring GPU clusters, Ollama runs efficiently on developer machines while supporting popular open-source models like Llama 2 and Mistral.

Local LLMs excel at processing sensitive documents, generating internal reports, answering employee questions, and automating customer support while keeping data private.

They're ideal for HR systems, legal document review, and proprietary knowledge management.

Smaller7B parameter models run well on modern laptops with 16GB RAM. For larger models, dedicated servers with GPUs provide better performance.

Quantized models balance between capability and resource usage for most business applications.

Local LLMs provide military-grade security since data never transmits externally.

When combined with proper network and access controls, they offer the highest level of confidentiality for sensitive business communications and document processing.

Yes, through automation platforms like n8n, local LLMs connect to CRMs, databases, and internal APIs while maintaining data isolation.

This creates AI-enhanced workflows without exposing information to third-party services.

GrowwStacks specializes in tailored AI automation solutions. Our team can design custom integrations between your existing systems and local LLMs.

We handle everything from model selection to deployment.

Need a Custom Local LLM Integration?

This free template is a starting point. Our team builds fully tailored automation systems for your specific needs.