n8n Data Processing File Conversion

Convert parquet, feather, ORC & Avro files with ParquetReader

Automate file conversion between columnar data formats using ParquetReader in n8n

Download Template JSON · n8n compatible · Free
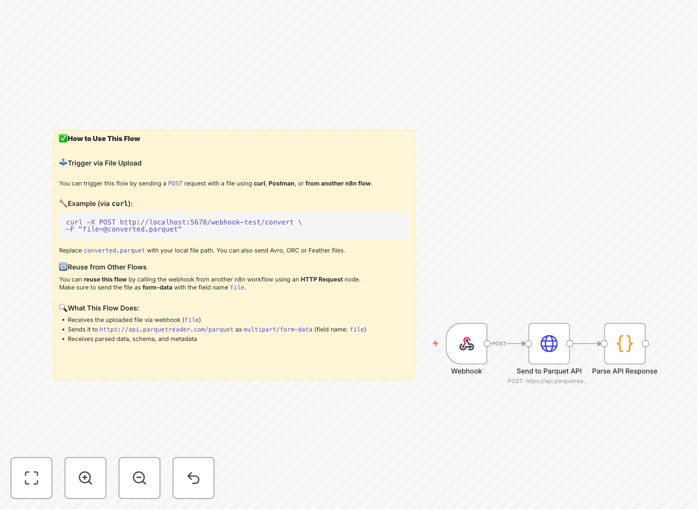
n8n workflow showing ParquetReader file conversion

What This Workflow Does

This n8n workflow template provides an automated solution for converting between various columnar data file formats including Parquet, Feather, ORC, and Avro. It leverages the ParquetReader node to efficiently process these specialized file formats commonly used in big data and analytics pipelines.

The workflow accepts file inputs from multiple sources (local uploads, cloud storage, or URLs) and converts them to your desired output format while maintaining data integrity. This eliminates manual conversion processes and ensures consistent handling of these complex file types.

How It Works

1. File Input

The workflow begins by accepting input files from your chosen source. You can configure it to receive files via direct upload, cloud storage integration (like S3 or Google Drive), or from a specified URL.

2. Format Detection

The system automatically detects the input file format (Parquet, Feather, ORC, or Avro) and prepares it for conversion. This step includes basic validation to ensure the file is properly formatted.

3. Conversion Processing

The ParquetReader node performs the actual conversion to your specified target format. You can configure output settings including compression options and schema preservation.

4. Output Delivery

Converted files are delivered to your specified destination. Options include local download, cloud storage upload, or forwarding to another system via API.

Who This Is For

This workflow is ideal for:

  • Data engineers working with multiple columnar data formats
  • Analytics teams needing to standardize incoming data files
  • ETL pipeline developers requiring format conversion capabilities
  • Business intelligence professionals preparing data for different tools

What You'll Need

  1. An n8n instance (self-hosted or cloud)
  2. Access to ParquetReader node (included in core n8n)
  3. Source files in Parquet, Feather, ORC, or Avro format
  4. Destination storage location (optional, if not using local download)

Quick Setup Guide

  1. Download and import the JSON template into your n8n instance
  2. Configure your input source (file upload, cloud storage, or URL)
  3. Set your desired output format and destination
  4. Test with sample files to verify conversion quality
  5. Deploy as part of your data processing pipeline

Key Benefits

Time Savings: Eliminate manual conversion processes that can take hours for large files. Automated conversion handles batches efficiently.

Data Integrity: Maintains schema and data quality during conversion, preventing common manual conversion errors.

Flexible Integration: Works with your existing storage solutions and can be triggered by various events in your data pipeline.

Pro tip: For large files, consider breaking them into smaller chunks before conversion to improve performance and reduce memory usage.

Frequently Asked Questions

Common questions about columnar data file conversion

Parquet is optimized for complex nested data with efficient compression and columnar storage. Feather is designed for fast read/write operations in Python/R environments. ORC is optimized for Hive/Spark workloads with ACID support. Avro provides row-based storage with schema evolution capabilities.

Each format has specific strengths: Parquet for analytics queries, Feather for Python/R interoperability, ORC for Hadoop ecosystems, and Avro for schema flexibility. The choice depends on your specific use case, toolchain, and performance requirements.

  • Parquet: Best for analytical queries on large datasets
  • Feather: Ideal for Python/R data exchange
  • ORC: Optimized for Hive/Spark processing

Conversion between formats is typically needed when moving data between different processing environments or when specific tools require particular formats. For example, converting Parquet to Feather when moving from Spark processing to Python analysis, or ORC to Avro when schema evolution is required.

A common scenario is receiving data in one format from a vendor or partner system while your analytics tools require a different format. Automated conversion ensures seamless data flow between different components of your data pipeline without manual intervention.

Conversion performance depends on file size, schema complexity, and hardware resources. Columnar-to-columnar conversions (like Parquet to ORC) are generally faster than columnar-to-row conversions. Memory usage can spike during conversion of large files.

For optimal performance, consider partitioning large files before conversion. Monitor resource usage during initial runs to determine appropriate batch sizes. Compression settings also significantly impact conversion speed and output file size.

  • Benchmark with sample files before processing full datasets
  • Adjust chunk size settings for large files
  • Consider parallel processing for batch conversions

The conversion process preserves the original schema by default. The workflow maps data types between formats while maintaining field names, types, and metadata. Complex nested structures are handled appropriately based on the capabilities of the target format.

Some format-specific features may not translate perfectly. For example, Avro's schema evolution capabilities don't directly transfer to Parquet. The workflow includes validation steps to identify any schema elements that might require special handling in the target format.

When automating file conversions, consider data sensitivity and implement appropriate access controls. Ensure temporary files during conversion are properly secured and cleaned up. Validate file contents before processing to prevent malicious payloads.

For sensitive data, implement encryption for files in transit and at rest. Use service accounts with minimal necessary permissions for cloud storage integrations. Audit conversion logs to maintain compliance with data governance requirements.

  • Implement input validation
  • Use secure connections for file transfers
  • Apply principle of least privilege to access controls

Yes, you can modify the workflow to include column selection or data filtering as part of the conversion process. The workflow includes a configuration option for column selection, allowing you to select only the columns you need before writing to the output file. This can significantly reduce file size and processing time when you only need a subset of the data.

To implement column selection, modify the field mapping configuration to include only the desired columns. You can add a filter node before the conversion step to remove unwanted rows based on your criteria. This approach is particularly useful when working with large datasets where you only need a specific subset of the data for analysis.

  • Column selection reduces processing time and output file size
  • Filtering can be based on any field values or conditions
  • Consider adding data transformation steps if needed

Absolutely! GrowwStacks specializes in building custom data processing automations tailored to your specific requirements. While this free template provides basic format conversion, we can develop enhanced solutions with additional features like schema validation, quality checks, parallel processing, and integration with your existing data pipeline.

Our team can build a complete file processing system that handles your unique file formats, validation rules, and destination requirements. We'll optimize performance for your specific data volumes and implement robust error handling and monitoring. Contact us for a free consultation to discuss your columnar data conversion needs.

  • Custom format support beyond the basic four formats
  • Integration with your specific storage systems and analytics tools
  • Enhanced error handling and notification systems
  • Performance optimization for your data volumes

Need a Custom Columnar File Conversion Solution?

This free template provides basic functionality. Our team builds fully customized file processing pipelines tailored to your specific data formats, volume, and integration requirements.