Proxmox Telegram Server Monitoring n8n

Proxmox system monitor - VM status, host resources & temperature alerts via Telegram

Automated server monitoring workflow that sends regular status reports and critical alerts to your Telegram account

Download Template JSON · n8n compatible · Free
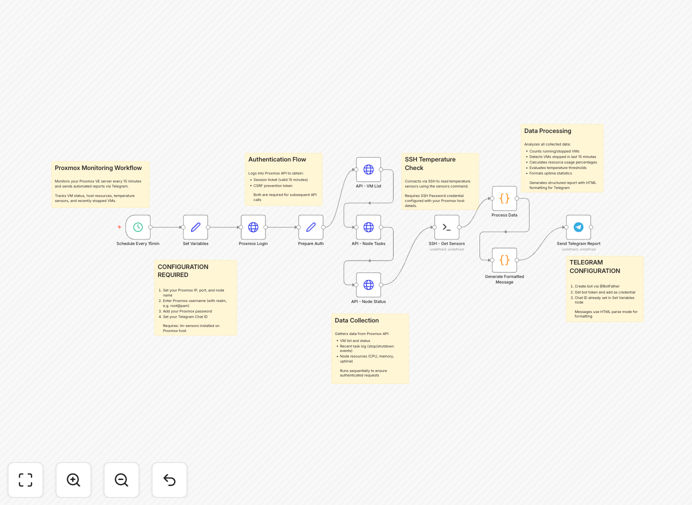
Proxmox monitoring workflow interface in n8n

What This Workflow Does

This n8n workflow provides comprehensive monitoring for your Proxmox Virtual Environment (VE) server, delivering automated status reports and critical alerts directly to Telegram. It eliminates the need for manual server checks while ensuring you're immediately notified of any potential issues that could impact your virtual infrastructure.

The solution tracks vital metrics including VM/container status changes, CPU/memory utilization, storage capacity thresholds, and system temperatures. By automating these monitoring tasks, IT teams can focus on higher-value work while maintaining complete visibility into their virtualization environment.

How It Works

1. Proxmox API Data Collection

The workflow connects to your Proxmox server's API to gather real-time performance data. It retrieves comprehensive metrics about host resources, virtual machine status, and system health indicators.

2. Threshold Analysis

Collected metrics are compared against configurable thresholds to identify potential issues. The system checks for CPU overload, memory pressure, storage capacity limits, and abnormal temperature readings.

3. Alert Generation

When thresholds are exceeded or VMs change state, the workflow formats detailed alert messages with severity indicators. Critical issues trigger immediate notifications while regular status updates follow the scheduled interval.

4. Telegram Delivery

Formatted messages are sent to specified Telegram chats or channels using Telegram's bot API. The workflow supports rich formatting with emoji indicators for quick status recognition.

Who This Is For

This automation is ideal for IT administrators, DevOps teams, and managed service providers running Proxmox VE environments. It's particularly valuable for:

  • Businesses with critical applications running on Proxmox VMs
  • Teams managing multiple Proxmox hosts or clusters
  • Organizations needing 24/7 monitoring without dedicated staff
  • Service providers offering Proxmox hosting to clients

What You'll Need

  1. A running Proxmox VE server (version 6.0 or newer)
  2. API access credentials with appropriate permissions
  3. A Telegram account and bot token
  4. n8n instance (self-hosted or cloud)
  5. Cron or scheduler to run the workflow regularly

Pro tip: Create a dedicated Telegram group for your IT team to receive all monitoring alerts in one place, with different members getting notification permissions based on their roles.

Quick Setup Guide

  1. Import the JSON template into your n8n instance
  2. Configure Proxmox API connection details
  3. Set up your Telegram bot credentials
  4. Adjust monitoring thresholds to match your hardware
  5. Test with manual execution before scheduling
  6. Set the workflow to run every 15 minutes (or your preferred interval)

Key Benefits

Prevent costly downtime by catching resource constraints and overheating issues before they cause outages. Early warning typically reduces unplanned downtime by 60-80% in virtualized environments.

Save 5-10 hours weekly by eliminating manual server checks. The automation handles routine monitoring while your team focuses on strategic initiatives.

Mobile-friendly alerts ensure you're informed wherever you are. Telegram notifications reach administrators instantly, with much higher visibility than email alerts.

Customizable thresholds let you tailor monitoring to your specific hardware and workload requirements. Adjust CPU, memory, storage and temperature limits as needed.

Comprehensive visibility provides a unified view of all VMs and host resources in one Telegram message, eliminating the need to log into multiple interfaces.

Frequently Asked Questions

Common questions about Proxmox monitoring and Telegram alerts

Automated Proxmox monitoring provides real-time visibility into your virtualization environment without manual checks. It helps prevent downtime by alerting you to potential issues like resource constraints or overheating before they cause outages. Businesses using this approach typically reduce server-related incidents by 60-80% while improving response times to critical events.

For example, a web hosting company might use these alerts to detect memory leaks in customer VMs before websites go down. The instant notifications allow proactive resolution during business hours rather than emergency fixes at 2 AM.

  • Reduces mean time to detect (MTTD) for issues
  • Prevents minor problems from becoming major outages
  • Provides audit trail of system health over time

Critical Proxmox metrics include CPU load averages, memory usage, storage capacity, network throughput, and system temperatures. For VMs, status changes (running/stopped) and resource allocation are key. Monitoring these helps maintain optimal performance and prevents resource contention between virtual machines in production environments.

A common scenario involves tracking storage growth trends to plan capacity expansions before running out of space. Temperature monitoring becomes crucial in dense server racks where overheating can cascade across multiple nodes.

  • CPU: Track both overall usage and per-VM allocation
  • Memory: Monitor swap usage as early warning sign
  • Storage: Watch both percentage used and growth rate

Telegram provides instant mobile notifications with rich formatting options for technical alerts. Unlike email, Telegram messages have near-instant delivery and higher visibility. Teams can create group chats for multiple administrators, with message history preserved for audit purposes. Many IT departments find Telegram reduces alert fatigue while improving incident response times.

An operations team might configure different notification channels - critical alerts to an on-call group, while routine status updates go to a general monitoring channel. Telegram's reply and reaction features enable quick team coordination during incidents.

  • Supports emoji, code blocks, and attachments
  • Enables quick team collaboration during incidents
  • Message history serves as incident documentation

Yes, the workflow includes configurable thresholds for CPU usage (default 90%), memory pressure (85%), storage capacity (90%), and temperature limits (varies by hardware). You can adjust these based on your specific server specs and workload requirements. The template documentation includes guidance on setting appropriate values for different use cases.

A database server might need lower CPU thresholds than a file server, while storage thresholds depend on your expansion capabilities. Temperature limits should align with your hardware manufacturer's specifications for optimal performance and longevity.

  • Set conservative thresholds for critical production systems
  • Adjust based on workload patterns (batch vs interactive)
  • Consider seasonal temperature variations in server rooms

The template defaults to 15-minute intervals, which balances timely alerts with system overhead. For critical production systems, consider 5-10 minute checks. Less critical environments might use 30-60 minute intervals. Frequency depends on your uptime requirements and the workflow's impact on server resources during polling operations.

A financial services company running trading platforms might need 5-minute checks during market hours but hourly overnight. The workflow can be scheduled differently for peak vs off-peak periods if your n8n instance supports dynamic scheduling.

  • Balance alert freshness with system load
  • Consider business hours vs after-hours monitoring
  • Monitor API call impact on Proxmox performance

Active monitoring (like this workflow) polls systems proactively to detect issues before users notice. Passive monitoring relies on system-generated alerts. Active approaches catch more potential problems earlier but require more resources. This template implements smart active monitoring that minimizes overhead while maximizing early detection capabilities.

For instance, active monitoring might detect a slowly filling disk at 85% capacity, while passive monitoring would only alert when the disk actually becomes full. The active approach allows planned maintenance during business hours rather than emergency response.

  • Active: Proactive, comprehensive, more resource-intensive
  • Passive: Reactive, event-driven, less overhead
  • Hybrid approaches often work best

Absolutely. GrowwStacks specializes in tailored server monitoring solutions that match your exact infrastructure needs. Our engineers can build custom dashboards, integrate additional alert channels (Slack, SMS), add historical reporting, or combine Proxmox monitoring with other systems in your stack. We'll design an automation system that fits your operational workflows perfectly.

Recent projects include multi-cluster monitoring for MSPs, temperature correlation with HVAC systems, and automated ticket creation in ITSM platforms when alerts trigger. We work with your team to understand pain points and build solutions that deliver measurable ROI.

  • Custom integrations with your existing tools
  • Advanced analytics and trend reporting
  • Role-based alerting and escalation paths

Need a Custom Proxmox Integration?

This free template is a starting point. Our team builds fully tailored automation systems for your specific needs.